FLUX.2 Klein 4B BF16
256–1024px resolution (16px steps). Default: 1024×1024, 4 steps. Guidance: 1.0 (fixed). Unified model for generation and multi-reference editing. Sub-second inference.
$0.001/img
Test AI image generation for free, then deploy via API.
Estimated cost: calculating… $0.00633/image
2 free images left
{
    "model": "ZImageTurbo_INT8",
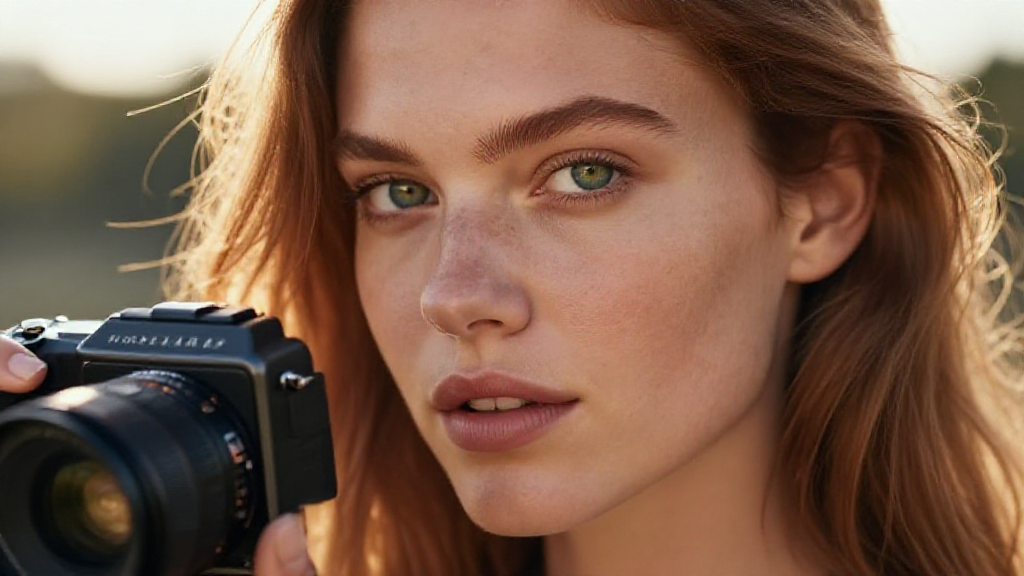
    "prompt": "Hyperrealistic portrait photograph of a beautiful young woman, natural skin texture with subtle freckles, piercing green eyes with realistic light reflections, soft volumetric lighting from golden hour sun, wispy strands of auburn hair catching the light, shallow depth of field, shot on Hasselblad medium format camera, 85mm lens, professional fashion photography, magazine cover quality, photorealistic skin pores and fine details, natural makeup, serene confident expression",
    "width": 1024,
    "height": 576,
    "steps": 8,
    "seed": 3471503624
}
curl -X POST \
  'https://api.deapi.ai/api/v2/images/generations' \
  -H 'Accept: application/json' \
  -H 'Authorization: Bearer {{ YOUR_API_TOKEN }}' \
  -H 'Content-Type: application/json' \
  -d '{
    "model": "ZImageTurbo_INT8",
    "prompt": "Hyperrealistic portrait photograph of a beautiful young woman, natural skin texture with subtle freckles, piercing green eyes with realistic light reflections, soft volumetric lighting from golden hour sun, wispy strands of auburn hair catching the light, shallow depth of field, shot on Hasselblad medium format camera, 85mm lens, professional fashion photography, magazine cover quality, photorealistic skin pores and fine details, natural makeup, serene confident expression",
    "width": 1024,
    "height": 576,
    "steps": 8,
    "seed": 3471503624
}'
Built for developers who need power without complexity.
256–1024px resolution (16px steps). Default: 1024×1024, 4 steps. Guidance: 1.0 (fixed). Unified model for generation and multi-reference editing. Sub-second inference.
Generate an image from a text prompt. Describe the subject, the layout, the lighting, the style and any text that should appear, then pick a size. The model returns the nearest of its fourteen aspect ratios at 1K, 2K or 4K.
Generate an image from a text prompt. Describe the subject, layout, lighting, style and any text that should appear, pick a size and a quality level, and get a finished frame without a reference image or sampler settings.
Text-to-image model built on Google's Gemini 3.1 Flash Image. Renders legible typography, follows long multi-part prompts, and delivers anything from photoreal portraits to labelled diagrams — up to 4096 x 4096 in a single pass.
· Experimental · Partner model · Premium · Generate from a description, with a reasoning pass ahead of generation. The gain is clearest on prompts with several interacting constraints — a layout with specified positions, a scene with a set number of objects, or a design that has to carry a specific line of text. Output runs from 512px up to 2048px.
Experimental · Partner model · Premium Generate from a plain-language description. GPT Image 1.5 follows long, compound instructions closely and renders legible text inside the image — useful for mockups, ad creative and anything carrying a label, sign or headline in frame.
INT8 quantized. Resolution 128–2048 px (16 px steps). 4–16 inference steps. Default: 768x768, 8 steps. Tuned with Z-Image Base for anime-style images. Recognizes several iconic characters from well-known anime.
256–2048px resolution (128px steps). 1–10 inference steps. Default: 768×768, 4 steps. No guidance needed. Optimized for speed.
Join developers & vibe coders building AI apps with deAPI. No credit card, zero setup headaches — just pure, instant AI magic.
Need enterprise pricing or SLA? Talk to Sales
You've reached your free daily limit
Your counter resets at 00:00 UTC.
Want to keep going? Register now and get $5 in free credits to start.
Quick check before we generate